San Diego Alignment Workshop

San Diego, California

•
December 1, 2025
December 2, 2025
Date Range

Program Committee

Adam Kalai

CSO

RESI

Divya Siddarth

Founder & Executive Director

Collective Intelligence Project

Roger Grosse

Associate Professor

Anthropic and University of Toronto

Atoosa Kasirzadeh

Assistant Professor

Carnegie Mellon University

Adam Gleave

Co-founder & CEO

FAR.AI

Overview

San Diego Alignment Workshop took place 1–2 December, 2025, immediately prior to the start of NeurIPS 2025 serving as a successor to the Alignment Workshops held in Singapore, San Francisco Bay Area, Vienna, New Orleans and San Francisco.

The program featured expert presentations, breakout discussions, and opportunities for one-on-one conversations.

The Alignment Workshop series brings together top machine learning researchers and practitioners from industry, academia, and government. The workshop focuses on discussing and debating critical topics related to AI alignment, enabling participants to better understand potential risks from advanced AI, and strategies for solving them. Key issues discussed include model evaluations, interpretability, robustness, and AI governance.

Speakers
Yoshua Bengio

LawZero / Mila / U. Montreal

Ben Buchanan

Johns Hopkins University

Samuel Bowman

Anthropic

David Elson

Google DeepMind

Alex Beutel

OpenAI

Johannes Heidecke

OpenAI

San Diego Alignment Workshop sessions

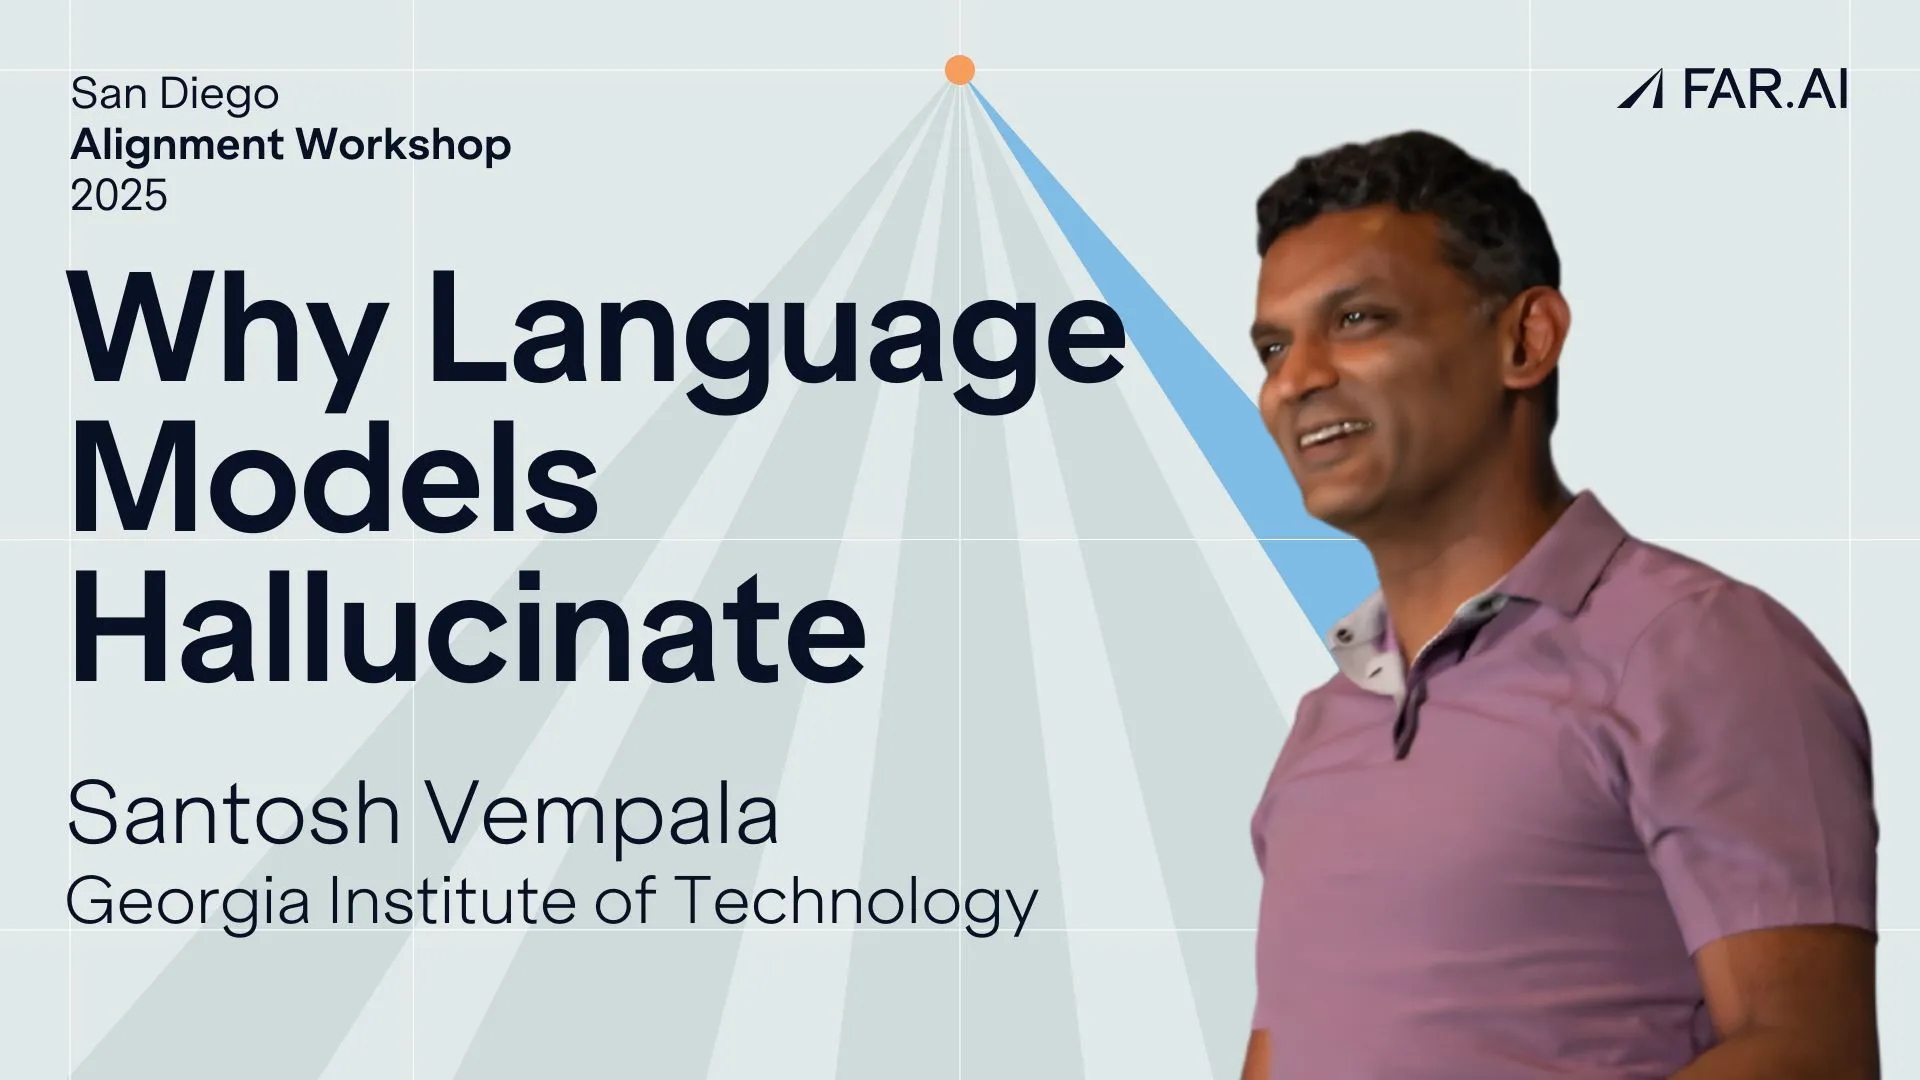
Why Language Models Hallucinate

Santosh Vempala

•

December 1, 2025

2025

What Does It Mean for Agentic AI to Preserve Privacy?

Niloofar Mireshghallah

•

December 1, 2025

2025

Toy Models for Task-Horizon Scaling

Cozmin Ududec

•

December 1, 2025

2025

The State and the Science of AI-Bio Evals

Bryce Cai

•

December 1, 2025

2025

State of Jailbreaks

Xander Davies

•

December 1, 2025

2025

Privacy and Security Challenges in AI Agents

Kamalika Chaudhuri

•

December 1, 2025

2025

Peril and Potentials of Training with Lie Detectors

Chris Cundy

•

December 1, 2025

2025

Our Pivot To Pragmatic Interpretability

Neel Nanda

•

December 1, 2025

2025

Measuring AI Systems’ Ability to Influence Humans

Anna Gausen

•

December 1, 2025

2025

How do we know what AI can (and can't) do?

Anka Reuel

•

December 1, 2025

2025

Hidden Pitfalls of AI Scientist Agents

Atoosa Kasirzadeh

•

December 1, 2025

2025

Guarding the Age of Agents

Bo Li

•

December 1, 2025

2025

Current State of AI Agent Security

Andy Zou

•

December 1, 2025

2025

AI + Democracy

Divya Siddarth

•

December 1, 2025

2025

Toward Scalable and Actionable Interpretability

Yonatan Belinkov

•

November 30, 2025

2025

Scalable Oversight and Understanding

Sarah Schwettmann

•

November 30, 2025

2025

San Diego Alignment Workshop 2025 Opening Remarks

Adam Gleave

•

November 30, 2025

2025

Provably Safe AI

Max Tegmark

•

November 30, 2025

2025

Powerful Open-Weight AI Models: Wonderful, Terrible & Inevitable

Stephen Casper

•

November 30, 2025

2025

Polarity-Aware Probing for Quantifying Latent Alignment in LMs

Chirag Agarwal

•

November 30, 2025

2025

Multi-agent RL for Provably Robust LLM Safety

Natasha Jaques

•

November 30, 2025

2025

Lessons Learned from the First Misalignment Safety Case

Samuel Bowman

•

November 30, 2025

2025

Frontier AI in Cybersecurity: Risks, Challenges & Future Directions

Dawn Song

•

November 30, 2025

2025

Finding & Reactivating Safety Mechanisms of Post-Trained LLMs

Yisen Wang

•

November 30, 2025

2025

Eval Awareness is Becoming a Problem

Marius Hobbhahn

•

November 30, 2025

2025

Disentangling Agency & Predictive Power Without Solving ELK

Yoshua Bengio

•

November 30, 2025

2025

Consensus Sampling for Safer Generative AI

Adam Kalai

•

November 30, 2025

2025

Chain of Thought Monitorability for AI Safety

Tomek Korbak

•

November 30, 2025

2025

Automating Mechanistic Interpretability

Chenhao Tan

•

November 30, 2025

2025

AI Control Needs Redteaming

Asa Cooper-Stickland

•

November 30, 2025

2025

AI Agent Benchmarks Are Broken

Daniel Kang

•

November 30, 2025

2025

A Practical Approach to Verifying Code at Scale

Maja Trębacz

•

November 30, 2025

2025