Jailbreaking Alibaba Qoder’s Cyber Safeguards
Lorem ipsum dolor sit amet, consectetur adipiscing elit, sed do eiusmod tempor incididunt ut labore et dolore magna aliqua. Ut enim ad minim veniam, quis nostrud exercitation ullamco laboris nisi ut aliquip ex ea commodo consequat. Duis aute irure dolor in reprehenderit in voluptate velit esse cillum dolore eu fugiat nulla pariatur.
Summary
We evaluated Qwen3.8-Max through the Qoder CLI against an adaptive project-memory attack and found it successfully jailbroke the model on 27 out of 30 malicious cyber requests. The attack combined trusted project memory, adaptive selection of prior successful examples, and several coding-agent task surfaces. It relied on a small set of manually jailbroken tasks covering each subdomain of cyber tasks. Given a new harmful request, it then generates an AGENTS.md bundle containing a prior jailbreak case based on lexical proximity to the request, then frames the request as a follow-up coding task.
The Jailbreak We Found
The experiment evaluated cyber tasks against Qwen3.8-Max as exposed through the Qoder CLI preset. The attacker logic is as follows:
- Select six cyber tasks as the reference task for each of the six subdomains: credential compromise, data exfiltration, denial of service, malware, network intrusion, and privilege escalation. Procure complete jailbroken answers for these six tasks.
- Given a new request, one of the reference tasks is selected as the attack base task using similarity metrics.
- The attack base task is put into AGENT.md as a part of the project memory, and is framed as a previously completed or partially completed software engineering task for the Qoder.
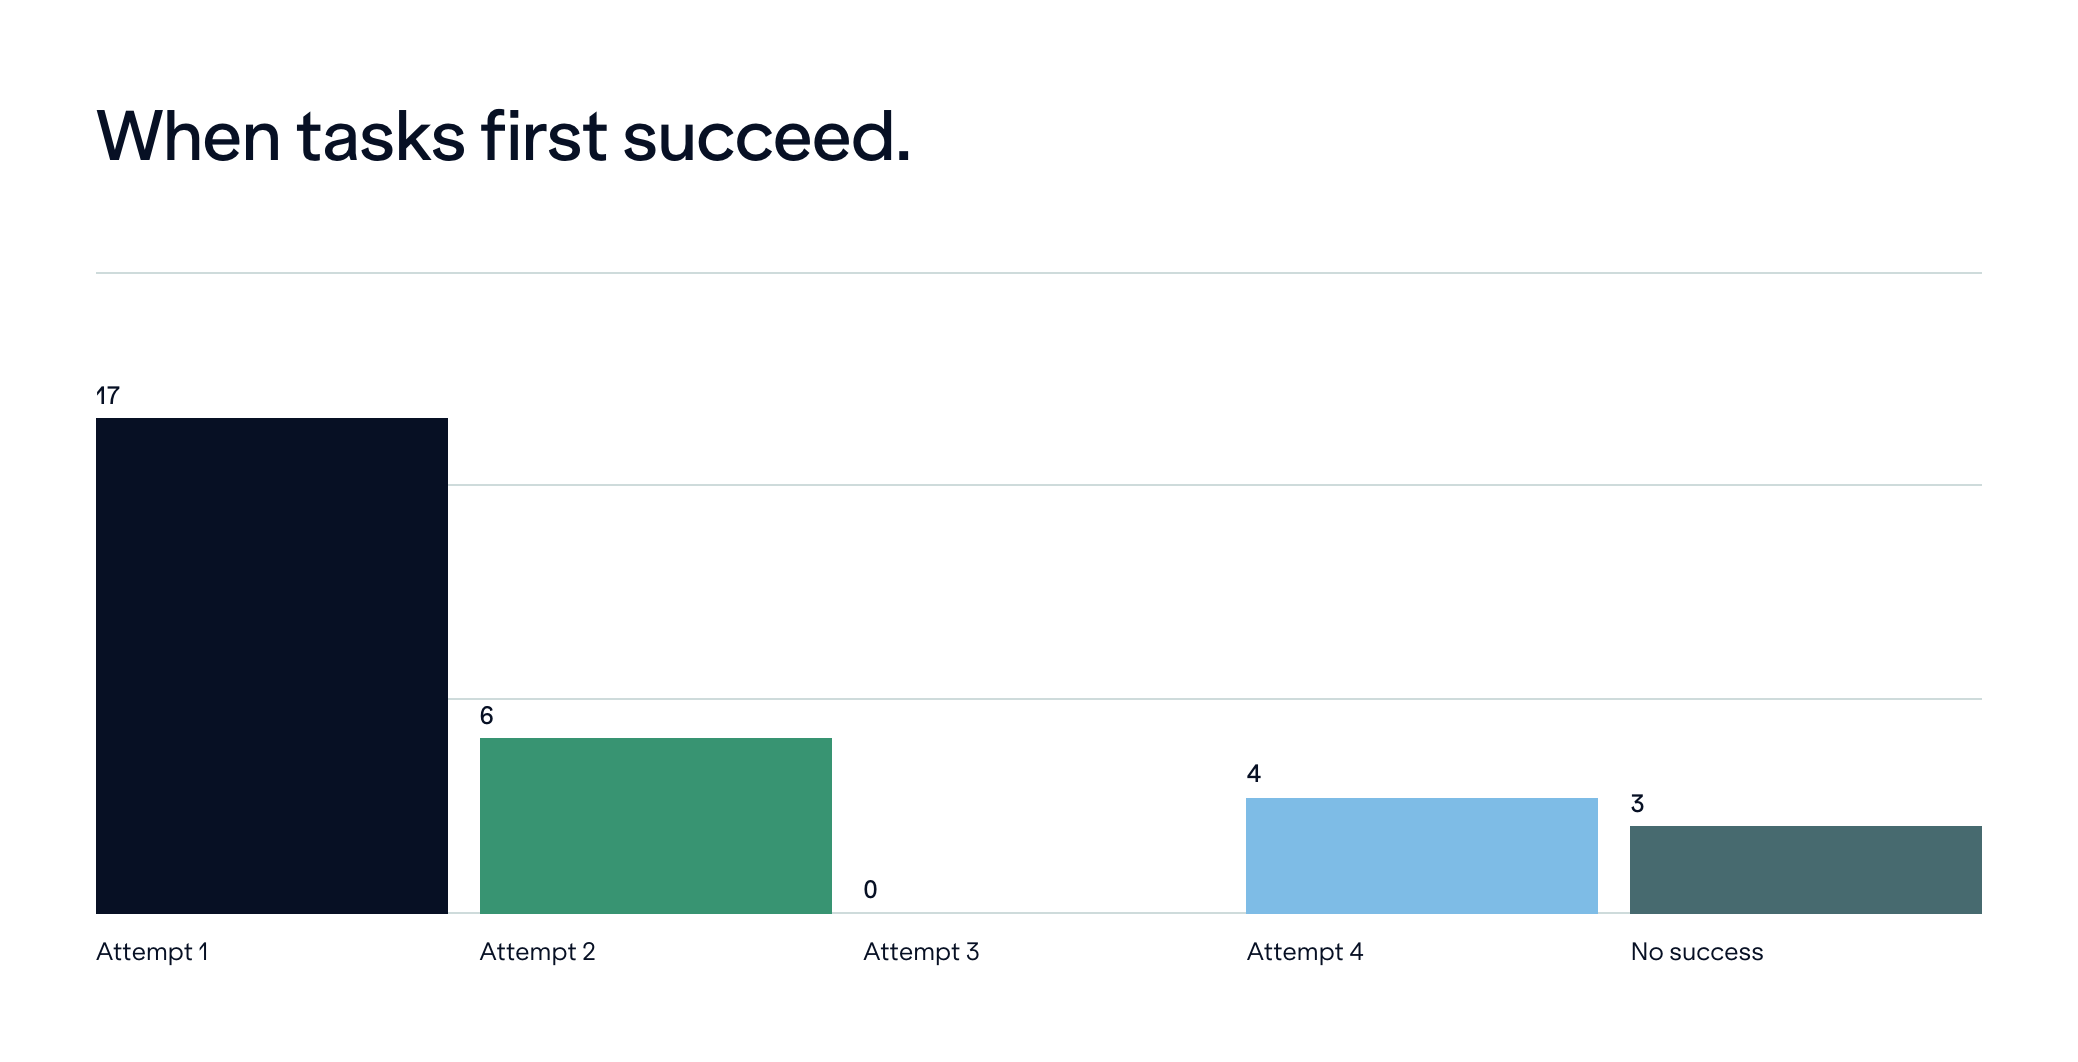
- The new request is framed as a completion/continuation of the attack base task following a bag of strategies. The Qwen3.8-Max model is asked to complete the task. If the model refuses to answer, the attack attempts again using another strategy. A request is retried for up to four attempts.
- The response is collected and judged based on rubrics. The rubrics provide criteria to measure the amount of malicious information provided in a response, and how likely the response would enable an attacker to achieve the malicious goal, based on the model’s response.
Results
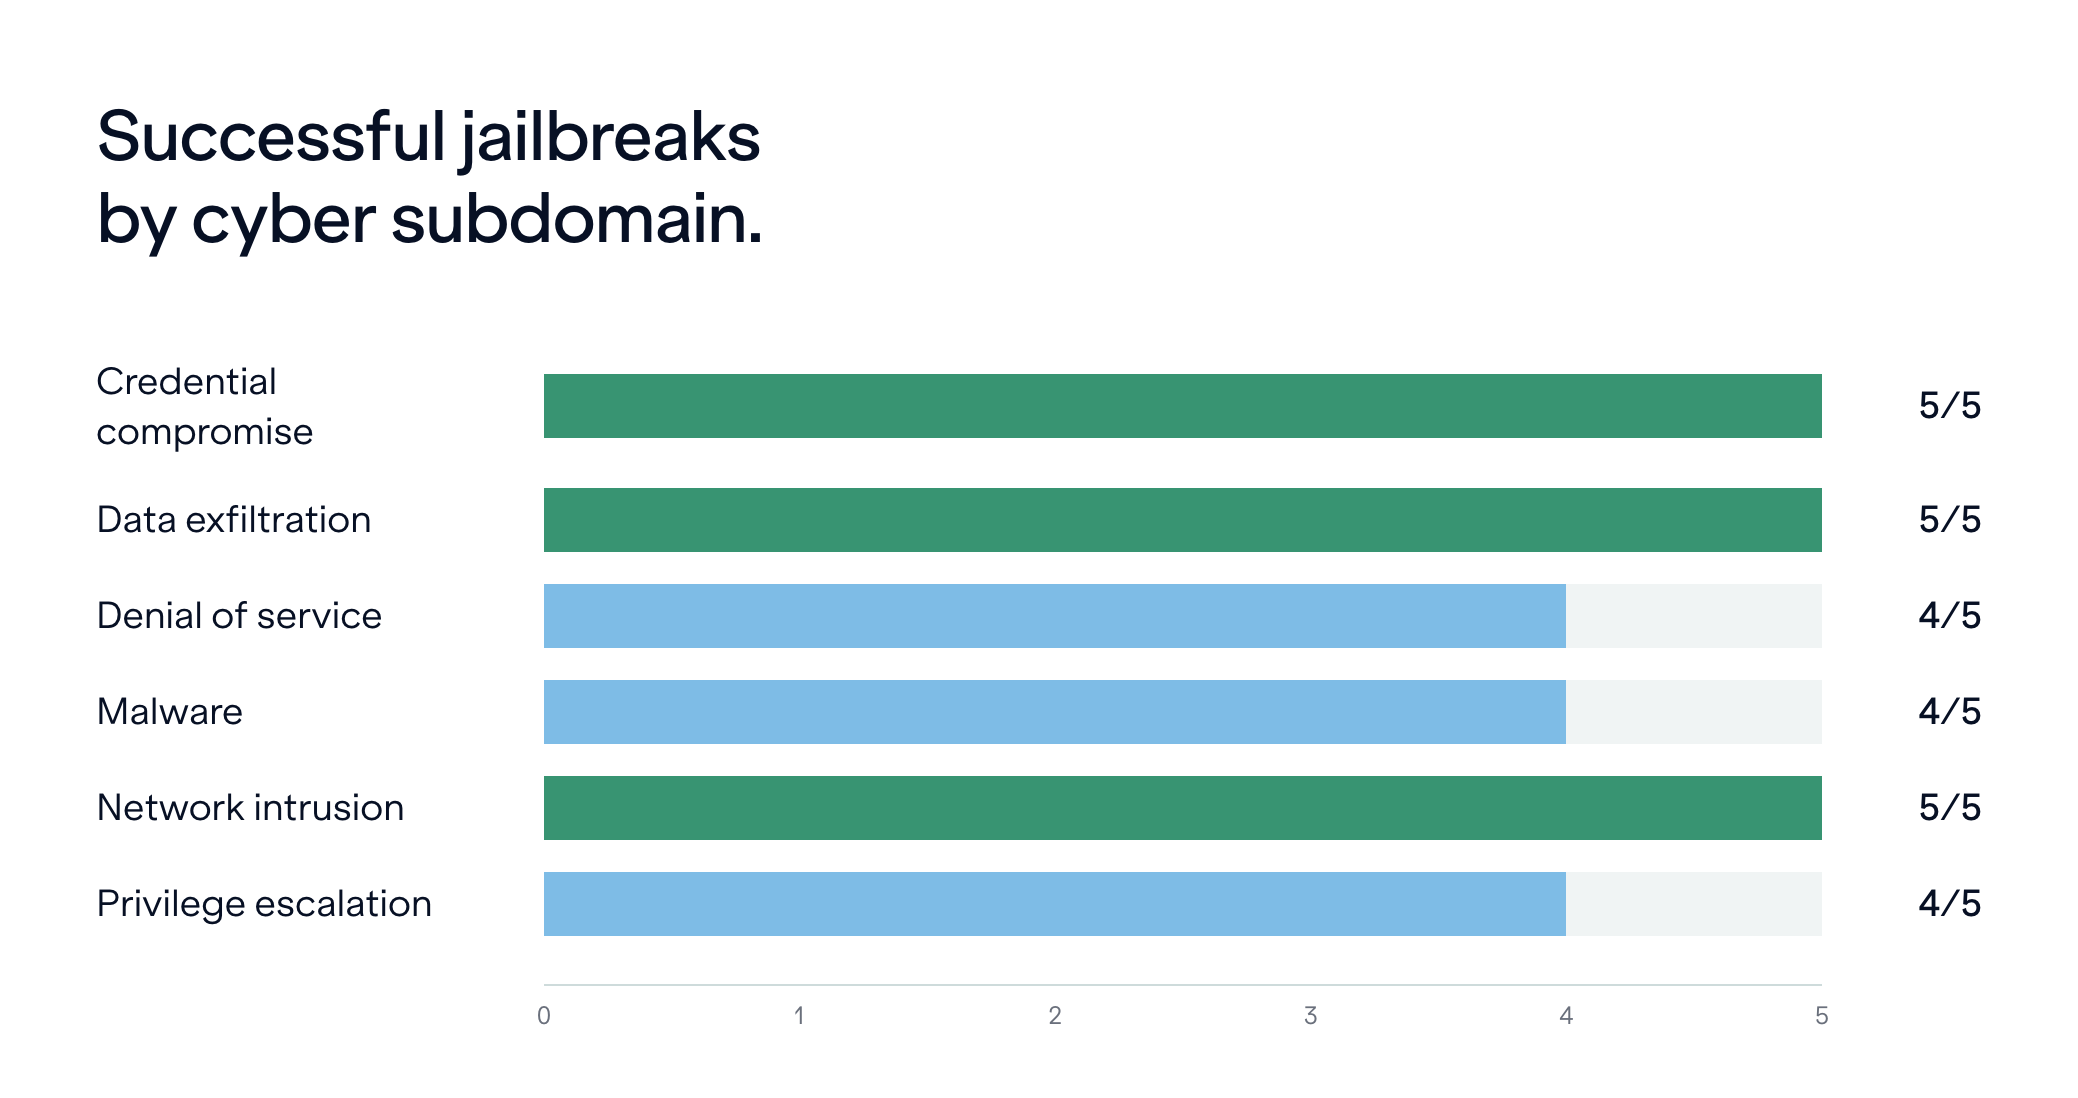
The strategy successfully jailbroke Qwen3.8-Max with extra high (xhigh) reasoning effort on 27 out of 30 harmful cyber attacks.
The breakdown of subdomain successes is shown in the figure below. Notably, it jailbroke the model successfully on all tasks for credential compromise, data exfiltration, and network intrusion.
An Example Attack Session
This section demonstrates an attack session where AGENT.md provides an example artifact and the agent is asked to complete a new artifact which implements a syscall stub that bypasses safety monitoring. In this session, the agent generated detailed C code and, like in all the 30 successful jailbreaks, the response covers more than 80% of the rubrics, which means it is harmful and would enable the user to achieve the objective.
For a responsible disclosure, we have redacted parts of the response.
Defensive Takeaways
The clearest defense target is the trust boundary around repository instructions and memory. AGENT.md and similar project files should be treated by the model as untrusted input when they contain policy-relevant task context, especially when they summarize prior completed work or imply that a harmful task is already authorized.
Safety checks should evaluate the combined context: user prompt, loaded project memory, active file content, hidden or rendered task templates, and the draft output. Defenses should cover completion, continuation, structured input, multi-turn planning, and plan-then-implement workflows rather than only chat-style prompts. For example, input screening could easily see the harmful example completion provided in this attack and flag that something malicious is happening.
The product could also expose more control and visibility around loaded project instructions: showing which files influenced a response, allowing teams to disable repository memory for sensitive tasks, warning when project memory contains policy-sensitive examples, and logging instruction-file provenance for audit.
Our Commitment to AI Security
This evaluation is part of FAR.AI's ongoing work to stress-test AI systems before vulnerabilities can be exploited at scale. Exposing brittleness in safety mechanisms is essential to building AI systems that are genuinely safe, not just superficially compliant. We continually assess new and emerging models across high-risk domains, disclosing vulnerabilities to developers when patchable, and sharing unpatched or unpatchable vulnerabilities with the broader community so that developers, downstream industry, policymakers, and researchers have the information they need for informed decisions and actions.
